
Argus Flow
An open-source data pipeline distribution that gathers everything you need to run Apache NiFi 2.10.0 in production. Custom extension bundles (NARs), deployment packages (tar.gz, RPM, container images), a Kubernetes operator, and configuration/certificate/user-management tooling — consolidated from scattered repositories into a single monorepo so every artifact ships from one build pipeline at matching versions.
Connect the extensions your NiFi pipelines need
Combine CDC or file listing, FlowFile processing, target writes and operational inspection.
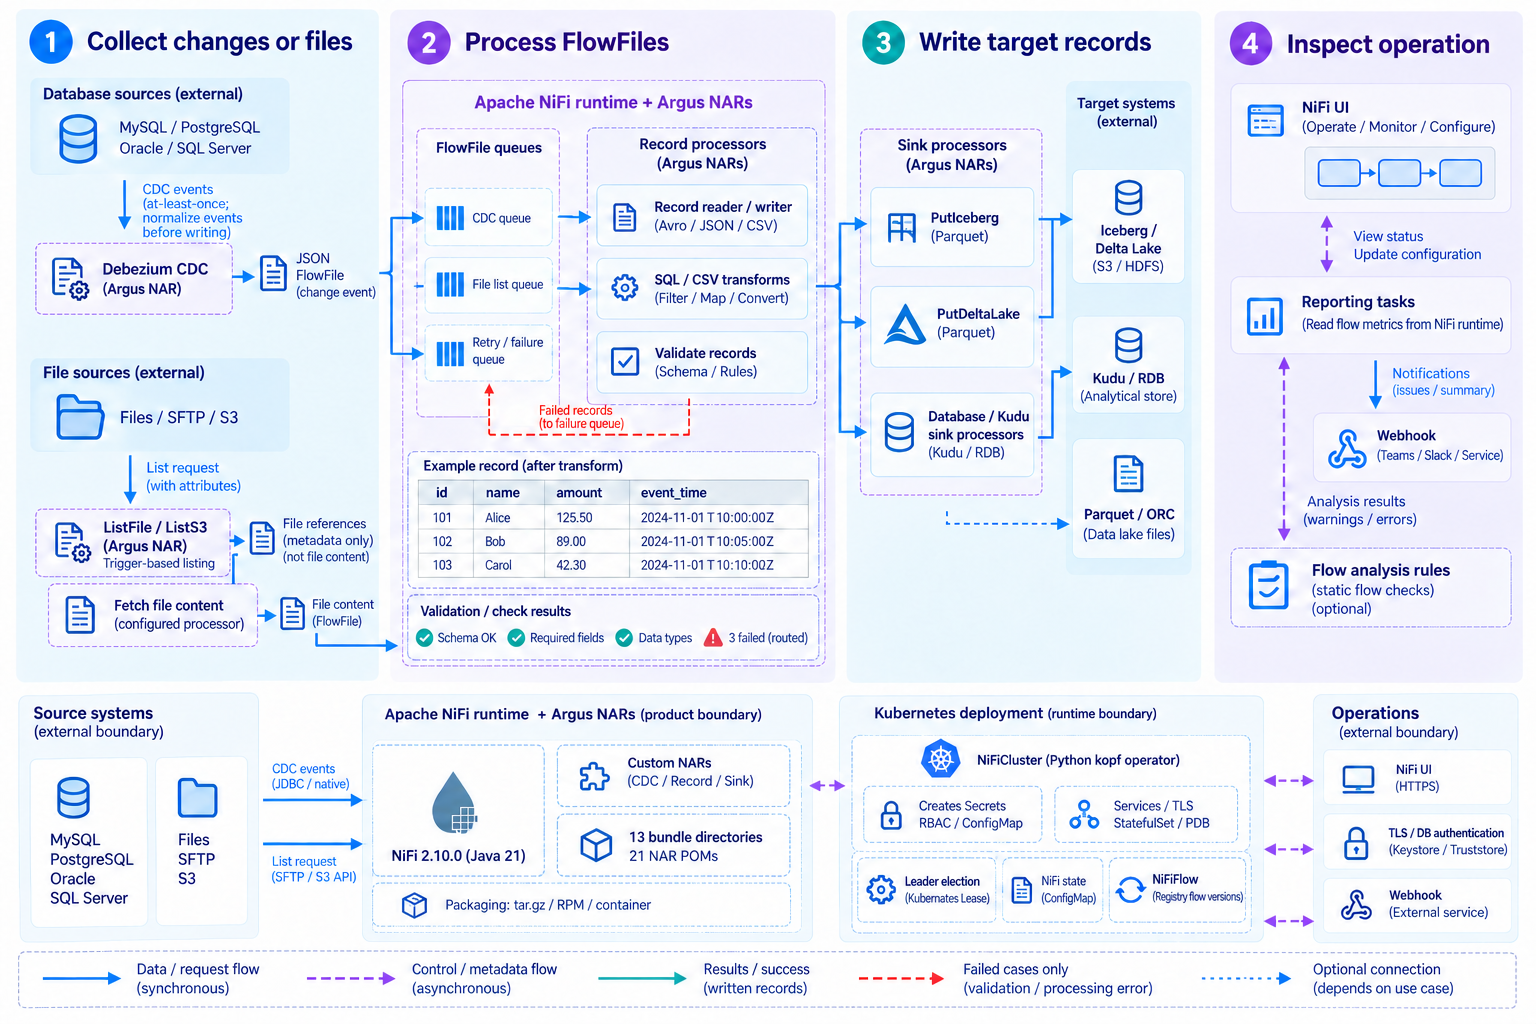
- 1.Collect changes or file listings
- Choose Debezium CDC or listing processors driven by incoming FlowFile attributes.
- 2.Process FlowFiles
- Connect NiFi queues and record readers/writers for transformation and routing.
- 3.Write target systems
- Write prepared records with PutIceberg, PutDeltaLake or PutDatabaseRecord.
- 4.Inspect operation
- Use the NiFi UI, reporting tasks and flow analysis rules to inspect runtime and configuration issues.
CDC uses at-least-once delivery. Configure event-to-record transformations for the target; listing files and fetching their contents are separate steps.
View GitHub documentation and codeFrom distribution build to Kubernetes operation
Package extensions, configure access and TLS, then manage declared clusters and flows with the operator.
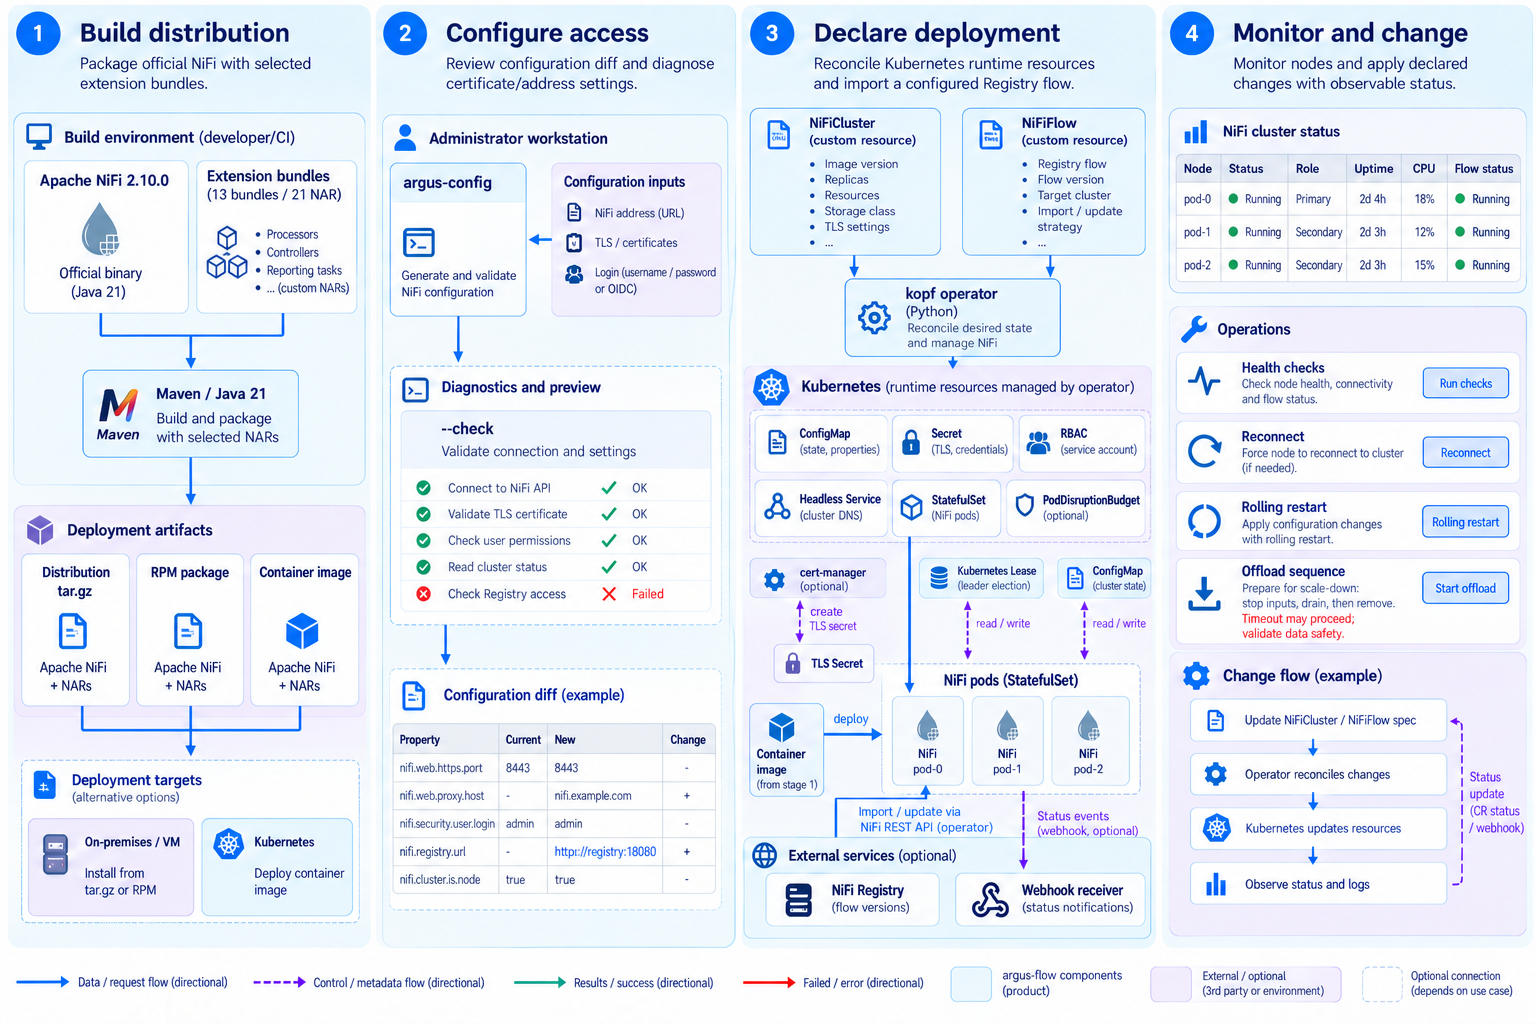
- 1.Build distribution
- Package official NiFi with extension NARs as tar.gz, RPM or container images.
- 2.Configure access
- Use argus-config for addresses, TLS and login; review diffs and diagnostics.
- 3.Declare deployment
- Specify runtime resources and Registry flow versions through NiFiCluster and NiFiFlow.
- 4.Monitor and change
- Use health checks, reconnection, rolling restarts and offloading procedures for operational changes.
The Kubernetes configuration uses Lease-based leader election and ConfigMap state management. Rolling restarts and scale-down do not guarantee uninterrupted or lossless operation.
View GitHub documentation and codeNiFi processors and controller services
30 processors for ingestion, queries, transformation and storage, plus 8 controller services for shared connections, serialization and catalogs.
Processors30 components
Processors handle FlowFiles. CDC uses at-least-once delivery, so configure duplicate, ordering and delete handling. Listing processors require a separate Fetch processor to retrieve file contents.
| Component | Category | Supported capabilities |
|---|---|---|
CaptureChangeMySQL | Change data capture | Captures row changes from the MySQL binlog as JSON FlowFiles. |
CaptureChangePostgreSQL | Change data capture | Captures PostgreSQL row changes through logical replication using pgoutput or decoderbufs. |
CaptureChangeOracle | Change data capture | Captures Oracle row changes through LogMiner, with CDB/PDB connection settings. |
CaptureChangeSQLServer | Change data capture | Reads row changes from SQL Server CDC tables and emits JSON FlowFiles. |
ExecuteSQL | Database | Streams SELECT results to Avro; supports bound parameters, schedules and incoming FlowFile triggers. |
ExecuteSQLRecord | Database | Streams SELECT results through a configurable Record Writer, with bound query parameters. |
ExecuteFastSQL | Database | Fetches SQL results with multiple threads and writes CSV; encodes binary values as Base64 and CLOBs as text. |
PutDatabaseRecord | Database | Converts records into SQL operations such as INSERT, UPDATE and DELETE, with transactions and success/retry/failure routing. |
BulkOracleInsertProcessor | Database | Loads records using parameterized Oracle INSERT ALL statements, with configurable batch size and query timeout. |
ListS3 | File listing | Lists S3 objects using incoming attributes for bucket/prefix; emits one FlowFile per object for FetchS3Object. |
ListHDFS | File listing | Lists an HDFS directory with attribute-driven paths and filters; passes file path attributes to FetchHDFS. |
ListFile | File listing | Lists local or mounted paths under an allowed base directory on the processing node; pairs with FetchFile. |
ListSFTP | File listing | Uses incoming attributes to select an SFTP endpoint and remote path; emits file listings for FetchSFTP. |
ListFTP | File listing | Uses incoming attributes to select an FTP endpoint and remote path; emits file listings for FetchFTP. |
QueryTrinoRecord | Trino queries & maintenance | Streams Trino SELECT results through a Record Writer with row-count splitting; records query IDs/statistics and cancels queries on stop. |
ExecuteTrinoStatement | Trino queries & maintenance | Executes one DDL/DML/ELT statement such as CTAS, INSERT SELECT or MERGE; supports synchronous/background and input-free scheduled runs. |
MaintainTrinoTable | Trino queries & maintenance | Runs Iceberg OPTIMIZE/snapshot expiry/orphan cleanup, Delta Lake OPTIMIZE/VACUUM, Hive partition synchronization, and ANALYZE for all three. |
PutIceberg | Lakehouse ingestion | Appends records to an existing Iceberg table using a Record Reader and catalog service; requires a compatible schema and separate CDC update/delete handling. |
PutDeltaLake | Lakehouse ingestion | Uses Delta Kernel to append Parquet files and commit the log of a path-based table; creates missing tables, with primitive types and file/HDFS as the baseline. |
PutKudu | Lakehouse ingestion | Writes records to Kudu with configurable operation, batching and flush mode; supports per-column timestamp formats and hour offsets. |
SelectHive3QL | Hive integration | Streams HiveQL SELECT results as Avro or CSV, with scheduling, input triggers and a result row-count attribute. |
PutHive3QL | Hive integration | Executes HiveQL DDL/DML from FlowFile content, binding placeholders through hiveql.args attributes. |
PutHive3Streaming | Hive integration | Loads records through the Hive 3 Streaming API using static partition values or partition fields in records. |
UpdateHive3Table | Hive integration | Creates a missing Hive table or adds columns/partitions to match the input schema before loading data. |
TriggerHiveMetaStoreEvent | Hive integration | Triggers Hive Metastore notifications from input paths and put/delete event attributes; requires a notification listener. |
PutORC | File formats | Reads records through a Record Reader and writes ORC files to the configured filesystem location. |
PutParquet | File formats | Writes records as Parquet using the configured schema, renaming the temporary file after a successful write. |
MergeParquet | File formats | Merges Parquet files from HDFS and reports the output path; can retain or delete source files after committing the merge. |
MultilineCsvParser | Transformation & commands | Streams CSV with multiline fields, configurable delimiters/encoding/quotes/headers/column counts, and failure routing for invalid input. |
PrePostExecuteStreamCommand | Transformation & commands | Passes FlowFile content to an external command and supports commands executed before and after it. |
Controller services8 components
Controller services share connection, reader, writer and catalog configuration across processors. Names match the actual components selected in NiFi.
| Component | Category | Supported capabilities |
|---|---|---|
CSVReader | Record readers & writers | Reads CSV rows as records using header-based schema inference or an explicit schema, with configurable timestamp formats. |
TimestampFormatAvroRecordSetWriter | Record readers & writers | Writes binary Avro with schema-property timestamp formats, hour offsets and compression settings. |
TimestampFormatParquetRecordSetWriter | Record readers & writers | Writes Parquet with schema-property timestamp formats, hour offsets and selectable INT96 fields. |
Hive3ConnectionPool | Database connections | Pools Hive 3 JDBC connections for Hive processors, with Kerberos integration. |
VendorHive3ConnectionPool | Database connections | Pools connections through an external vendor Hive JDBC driver, with service-specific driver locations and Kerberos; supply the driver JAR separately. |
HiveCatalogService | Iceberg catalogs | Connects to Hive Metastore to manage Iceberg table metadata and serves as a catalog for PutIceberg. |
HadoopCatalogService | Iceberg catalogs | Provides a filesystem-based Iceberg catalog for HDFS or similar filesystems supporting atomic rename. |
StandardTrinoConnectionService | Database connections | Provides unpooled Trino JDBC connections compatible with DBCPService; supports NONE/PASSWORD/JWT/Kerberos/OAuth2, session properties and external driver JARs. |
PostgreSQL CDC as a concrete NiFi flow
Connect logical replication to JSON events, destination-specific transformations and recovery.
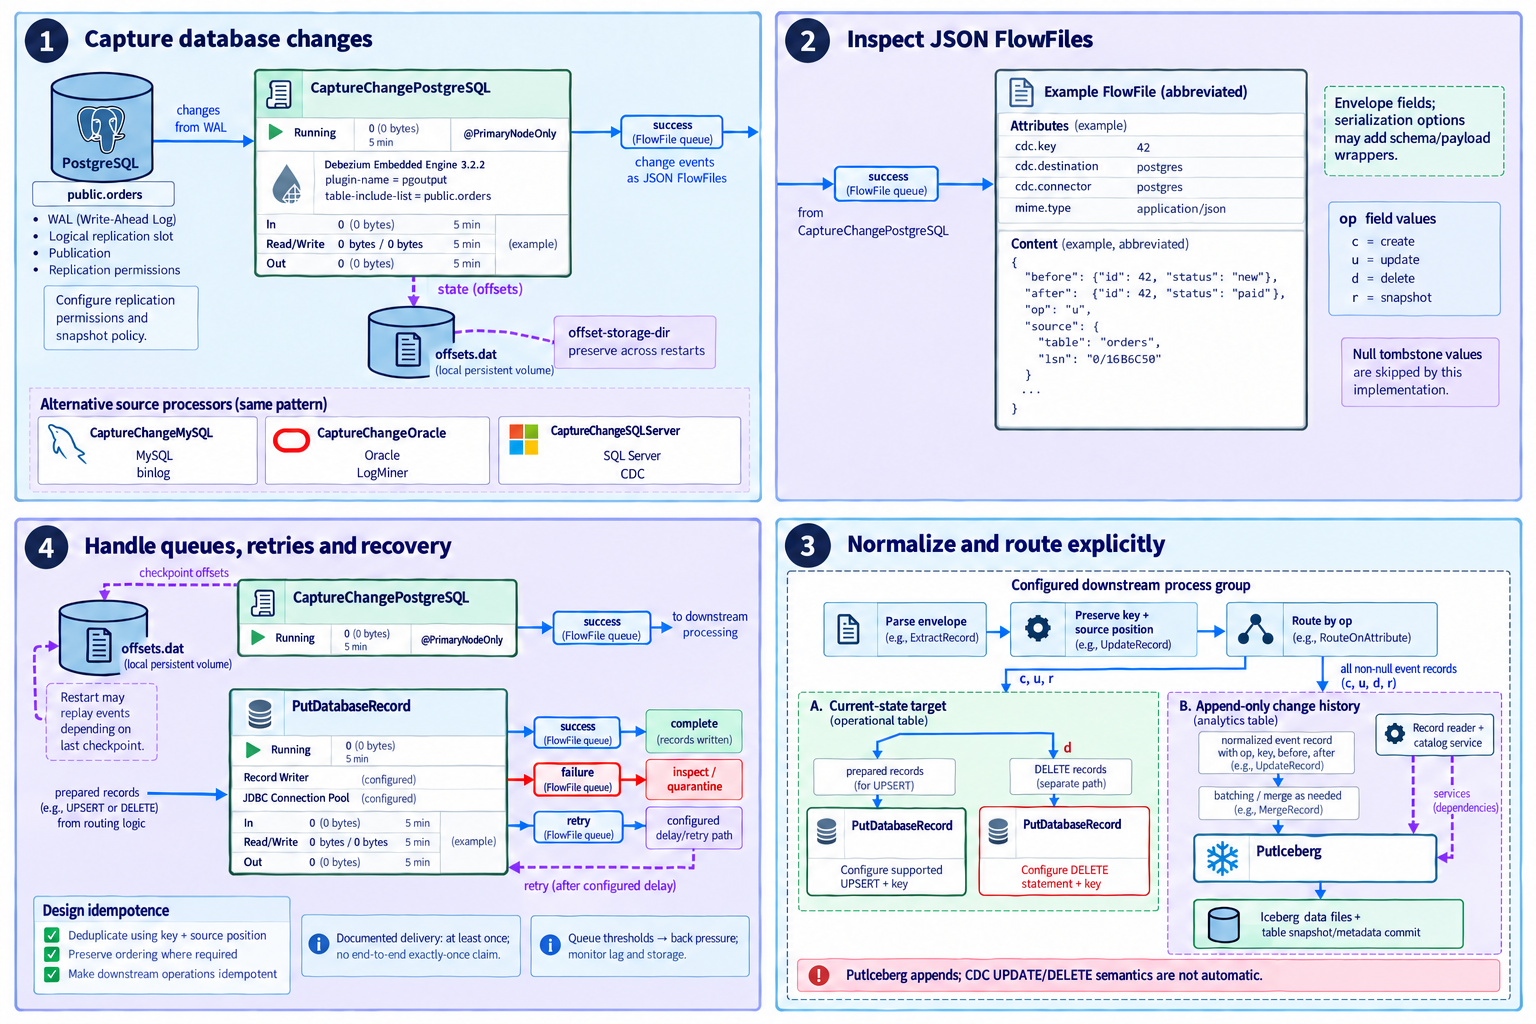
- 1.Configure logical replication
- Prepare permissions, slot and publication, then configure CaptureChangePostgreSQL and persistent local offsets.
- 2.Inspect events
- Check before, after, op and FlowFile attributes such as cdc.key.
- 3.Apply target semantics
- Separate current-state UPSERT/DELETE handling from append-only change history.
- 4.Plan recovery
- Configure destination failure/retry queues and deduplication for replayed events.
CDC documentation specifies at-least-once delivery. Deduplication, ordering and delete handling need explicit configuration. PutIceberg append writes do not automatically merge, update or delete CDC rows.
View GitHub documentation and codeDeployment, security, operational checks and editions
Review the public distribution’s operational capabilities alongside Enterprise support and services.
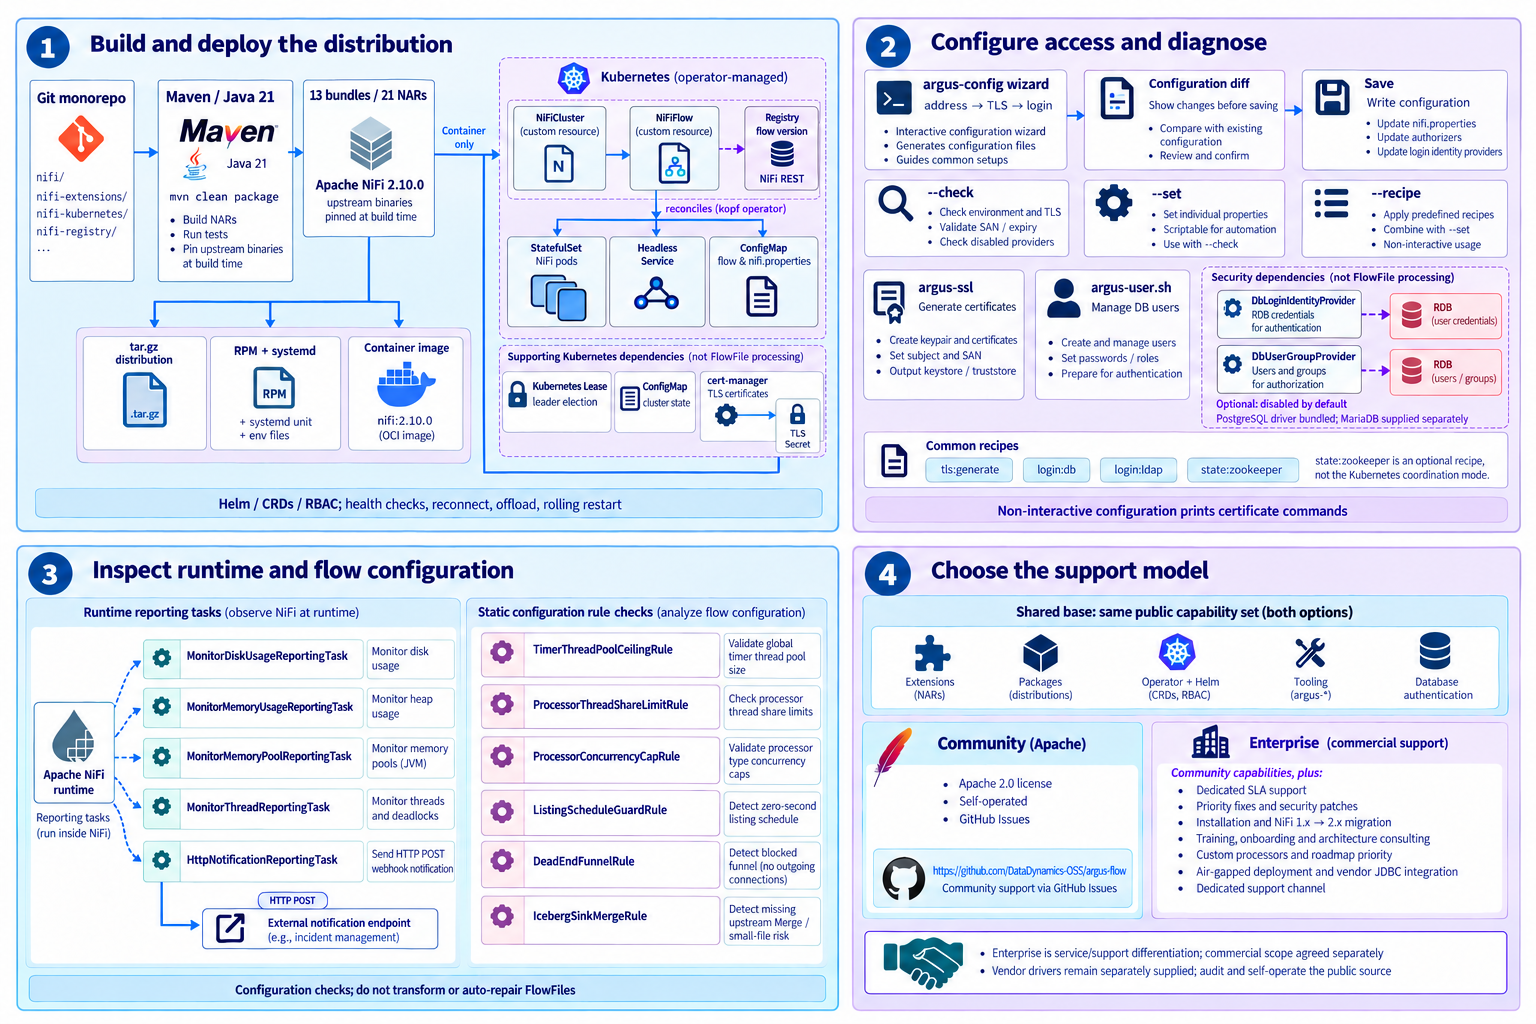
- 1.Assemble deployment
- Package 13 bundles and 21 NARs; Kubernetes uses Lease election and ConfigMap state.
- 2.Configure access
- Diagnose address, TLS and login settings; optionally enable database authentication and authorization.
- 3.Inspect operation
- Use five reporting tasks and six static rules to check runtime and flow configuration.
- 4.Choose support
- Select self-operated Community or Enterprise SLA, migration and custom development services.
Extensions, packaging, operator and tooling are public Community capabilities. Enterprise adds SLA support and professional services; vendor drivers are separately supplied. Rolling restarts and scale-down do not guarantee uninterrupted or lossless operation.
View GitHub documentation and codeA NiFi production distribution released as open source
Argus Flow is published on GitHub under the Apache License 2.0. Extension bundle sources, distribution packaging, the Kubernetes operator, and the operations tooling are all open, so enterprises can audit the code, extend it for their own environment, and run it entirely on their own — even in air-gapped networks.
- Apache 2.0 with no commercial-use restrictions
- Upstream attribution and license headers verified in the build
- Self-operated on-premises or air-gapped